Multidimensional Angular Model (RGB visualization)
Research provenance
This notebook accompanies Multi-sensory Integration in a Quantum-Like Robot Perception Model, published in Experimental Robotics (2021); the preprint is arXiv:2006.16404. Its RGB visualizations are paper-specific and intentionally remain in this notebook.
import matplotlib.pyplot as plt
import numpy as np

from qrobot.bursts import ZeroBurst
from qrobot.models import AngularModel
In this notebook we present a 3-dimensional (\(n=3\)) demo for the
AngularModel class. For simplicity, we consider \(\tau = 1\).
n = 3
tau = 1
Note: The RGB analogy provides an intuitive picture of three normalized sensor channels; it is a visualization device, not a claim that the model learns a color concept.
Input definition
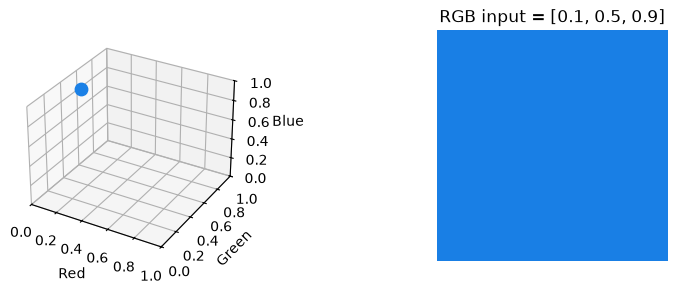
We start by defining an arbitrary normalized three-channel input:
input_data = [0.1, 0.5, 0.9]
plot_rgb_input(input_data)
Encode the input in the model
We initialize the model by instantiating an object with \(n\) and \(\tau\)
model = AngularModel(n, tau)
Encoding a general multidimensional sequence requires one call per temporal sample. The model maps each vector element to its corresponding dimension. This example has \(\tau = 1\), so the single event requires one encoding call:
model.clear()  # Keep this cell repeatable by discarding any earlier encoding.
model.encode_vector(input_data)
[0.3141592653589793, 1.5707963267948966, 2.827433388230814]
The model is implemented by a Qiskit quantum circuit:
model.print_circuit()
      ┌──────────┐
q_0: ─┤ Ry(π/10) ├
      ├─────────┬┘
q_1: ─┤ Ry(π/2) ├─
     ┌┴─────────┴┐
q_2: ┤ Ry(9π/10) ├
     └───────────┘
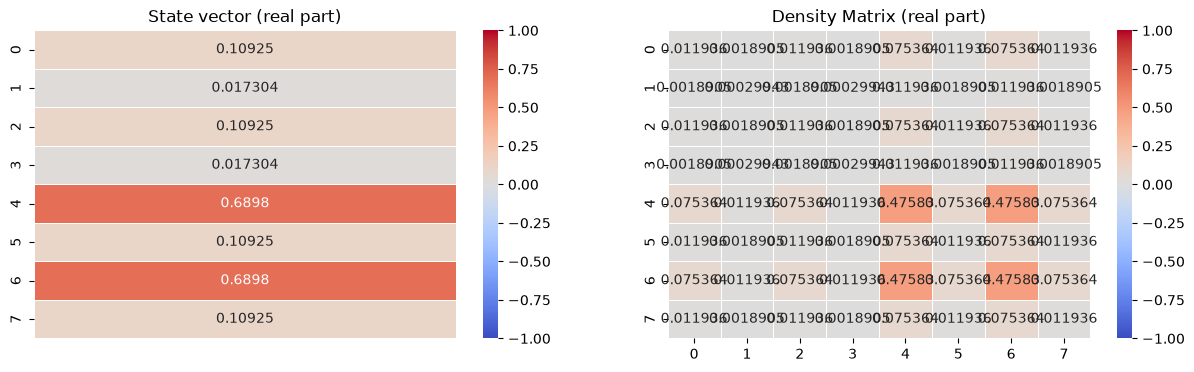
Given the input we defined above, the model is in the following state:
plot_encoded_model_state(model)
Measurement simulation
We simulate shots measurements, and then we extract the relative frequencies for the \(2^n\) possible basis state outcomes:
shots = 1000000
counts = model.measure(shots)
Raw counts for each possible outcome:
import json

print("Aggregated binary outcomes of the circuit:")
print(json.dumps(counts, sort_keys=True, indent=4))
Aggregated binary outcomes of the circuit:
{
    "000": 11907,
    "001": 282,
    "010": 12001,
    "011": 336,
    "100": 476141,
    "101": 11811,
    "110": 475652,
    "111": 11870
}
From the raw counts we can obtain the relative frequencies (aka the probabilities) and compare them with the input sequence. Since we have not operated any change of basis (with the model.query(target) method), the canonical basis is maintained, and it is possible to visualize it still with our RGB representation:
plot_canonical_measurements(input_data, counts, shots)
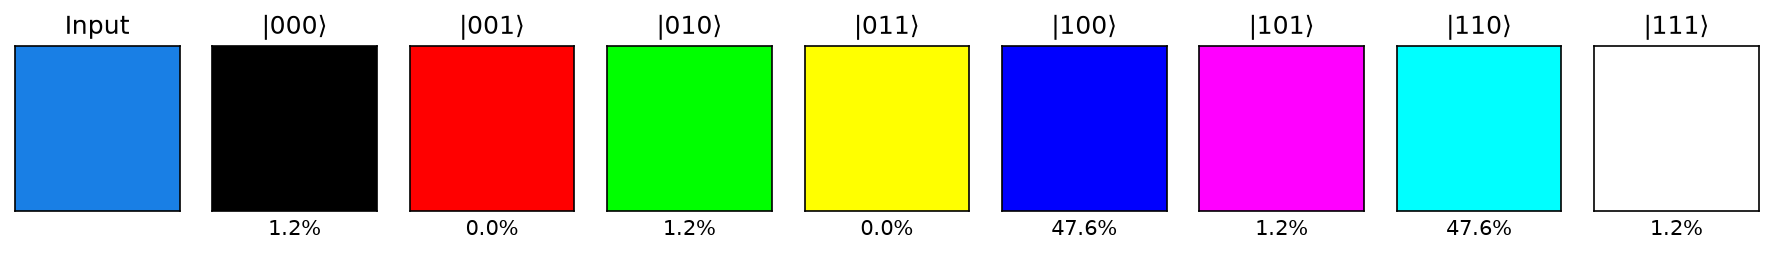
This shows how the two states which are more likely to be measured are the “blue” \(|100\rangle\) and “cyan” \(|110\rangle\) ones, which are the closes to our “blue-ish” input.
Measurement changes w.r.t. varying input
We can now move the input through RGB space and observe how the probability of each canonical basis state changes. We define this set of inputs:
input_positions = np.linspace(0, 1, 101)
path_positions = np.linspace(0, 1, 6)
path_colors = np.asarray(
    [
        [0.0, 0.0, 0.0],  # black
        [0.2, 0.9, 0.1],  # green-ish
        [1.0, 1.0, 1.0],  # white
        [0.9, 0.2, 0.1],  # red-ish
        [0.2, 0.1, 0.9],  # blue-ish
        [0.0, 0.0, 0.0],  # black
    ]
)
input_colors = np.column_stack(
    [np.interp(input_positions, path_positions, path_colors[:, channel]) for channel in range(3)]
)
plot_input_color_path(input_colors, path_positions)
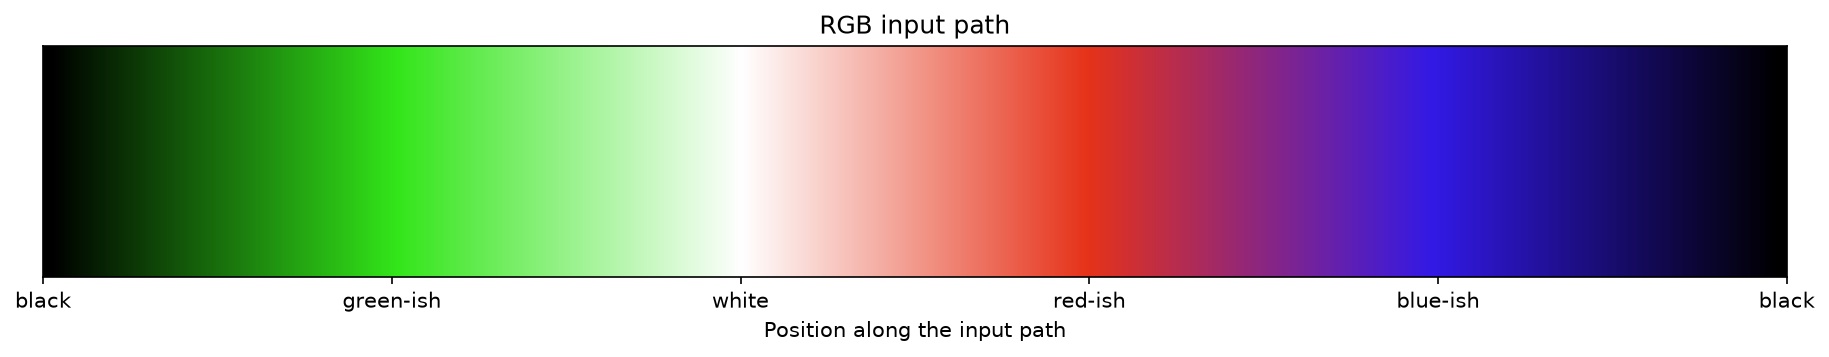
The color strip renders the input at every position. We now want to see how the probabilities of measuring each of the eight canonical basis states changes with the input. For every point on the input domain, we create a fresh model, encode its three RGB components, and read the exact probability of every basis state from the statevector:
state_labels = [f"{index:03b}" for index in range(8)]
canonical_probabilities = {state: [] for state in state_labels}
state_rgb_colors = {state: tuple(float(bit) for bit in reversed(state)) for state in state_labels}

for input_color in input_colors:
    sliding_model = AngularModel(n=3, tau=1)
    for dim, value in enumerate(input_color):
        sliding_model.encode(value, dim)
    probabilities = np.abs(sliding_model.get_statevector()) ** 2
    for index, state in enumerate(state_labels):
        canonical_probabilities[state].append(probabilities[index])
plot_canonical_input_sweep(input_positions, input_colors, canonical_probabilities, state_rgb_colors)
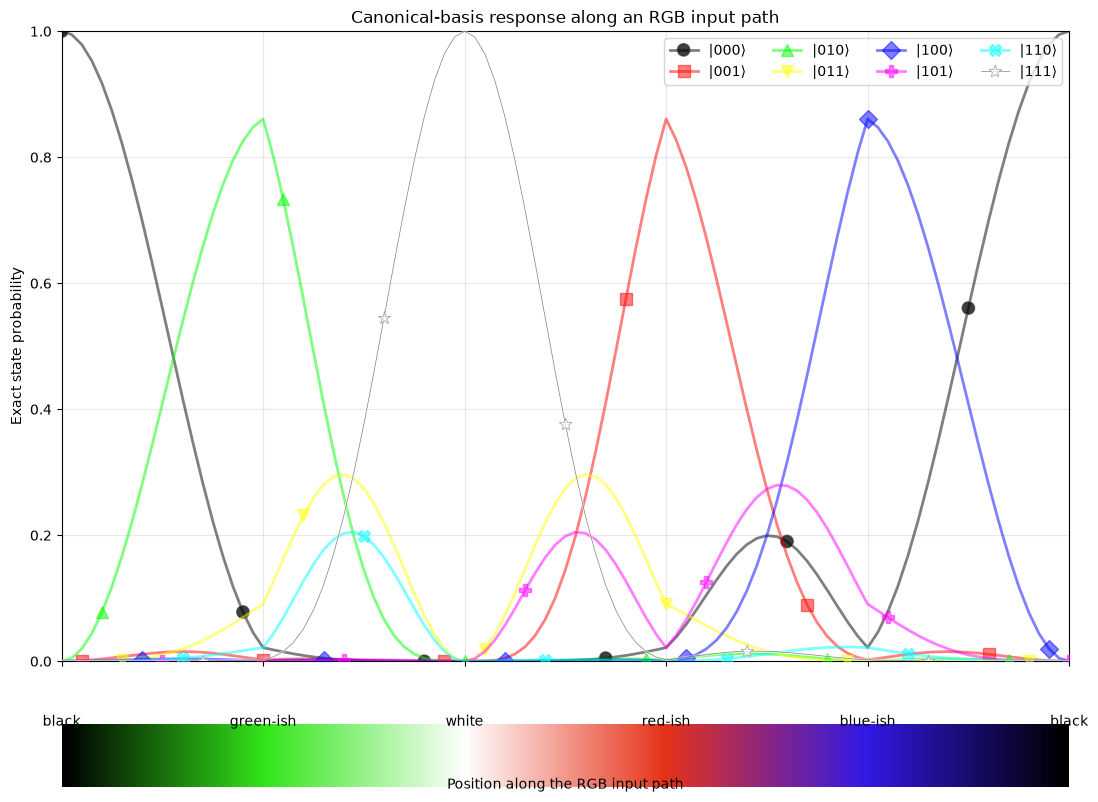
As the input reaches each color stop, probability concentrates on the nearest
canonical RGB corner: \(|000\rangle\) at black, \(|010\rangle\) near green,
\(|111\rangle\) at white, \(|001\rangle\) near red, and \(|100\rangle\) near blue.
Between those stops, several basis states remain probable because each channel
is encoded continuously rather than rounded to 0 or 1. Some curves overlap
when different states receive the same probability; their distinct markers
make those coincident outcomes visible.
From an RGB path to the whole input cube
The path above visits only a thin slice of the input domain. Does the same behavior hold away from that path? We now reproduce the two whole-RGB-space visualizations from the study cited above: the three probability cubes and the overlapping probability clouds plotted against distance from black. We still use \(n=3\), \(\tau=1\), and the canonical basis, with no query applied.
For one channel, encoding \(x_i\) prepares \(\cos(\pi x_i/2)|0\rangle+\sin(\pi x_i/2)|1\rangle\). Since these three qubits are independent, the probability of a complete bit string is a product:
Here \(x_0,x_1,x_2\) are red, green, and blue. Qiskit displays the bits as \(s_2s_1s_0\), so the red corner is \(|001\rangle\). We evaluate this expression in a batch instead of simulating a million shots for every input. This gives the exact probabilities underlying the paper’s sampled estimates.
rgb_levels = np.arange(0, 256, 5)
rgb_grid = np.stack(
    np.meshgrid(rgb_levels, rgb_levels, rgb_levels, indexing="ij"), axis=-1
).reshape(-1, 3)
normalized_rgb_grid = rgb_grid / 255.0


def rgb_basis_probabilities(colors):
    """Exact tau=1 probabilities, in Qiskit's |blue green red> order."""
    colors = np.asarray(colors)
    probability_zero = np.cos(np.pi * colors / 2) ** 2
    probability_one = np.sin(np.pi * colors / 2) ** 2
    bits = (np.arange(8)[:, None] >> np.arange(3)) & 1
    return np.prod(
        np.where(bits[None, :, :], probability_one[:, None, :], probability_zero[:, None, :]),
        axis=-1,
    )


rgb_probabilities = rgb_basis_probabilities(normalized_rgb_grid)
print(f"{len(rgb_levels)} levels per channel; {len(rgb_grid):,} RGB inputs")

# Check the formula against actual circuits, including every RGB corner.
check_colors = np.vstack(
    (
        [[float(bit) for bit in reversed(state)] for state in state_labels],
        [input_data, [0.5, 0.5, 0.5], [0.23, 0.61, 0.87]],
    )
)
for color, expected in zip(check_colors, rgb_basis_probabilities(check_colors), strict=True):
    check_model = AngularModel(n=3, tau=1)
    check_model.encode_vector(color)
    np.testing.assert_allclose(expected, np.abs(check_model.get_statevector()) ** 2, atol=1e-14)
np.testing.assert_allclose(rgb_probabilities.sum(axis=1), 1, atol=1e-14)
52 levels per channel; 140,608 RGB inputs
We include both 0 and 255: a step of 5 gives 52 levels and 140,608 inputs. The paper reports 132,651 alongside a step-of-5 description; that count does not match the inclusive grid used here. The axes retain the original 0–255 RGB units, while the model receives normalized values.
Probability landscapes at three canonical corners
Each point’s position is an RGB input, but its heat color is the probability of the outcome named above that cube. The common scale runs from black (zero) to white (one); it does not depict the input’s own RGB color. Blue rings mark the corresponding canonical corners, as in the original figure.
plot_rgb_probability_cubes(rgb_grid, rgb_probabilities)
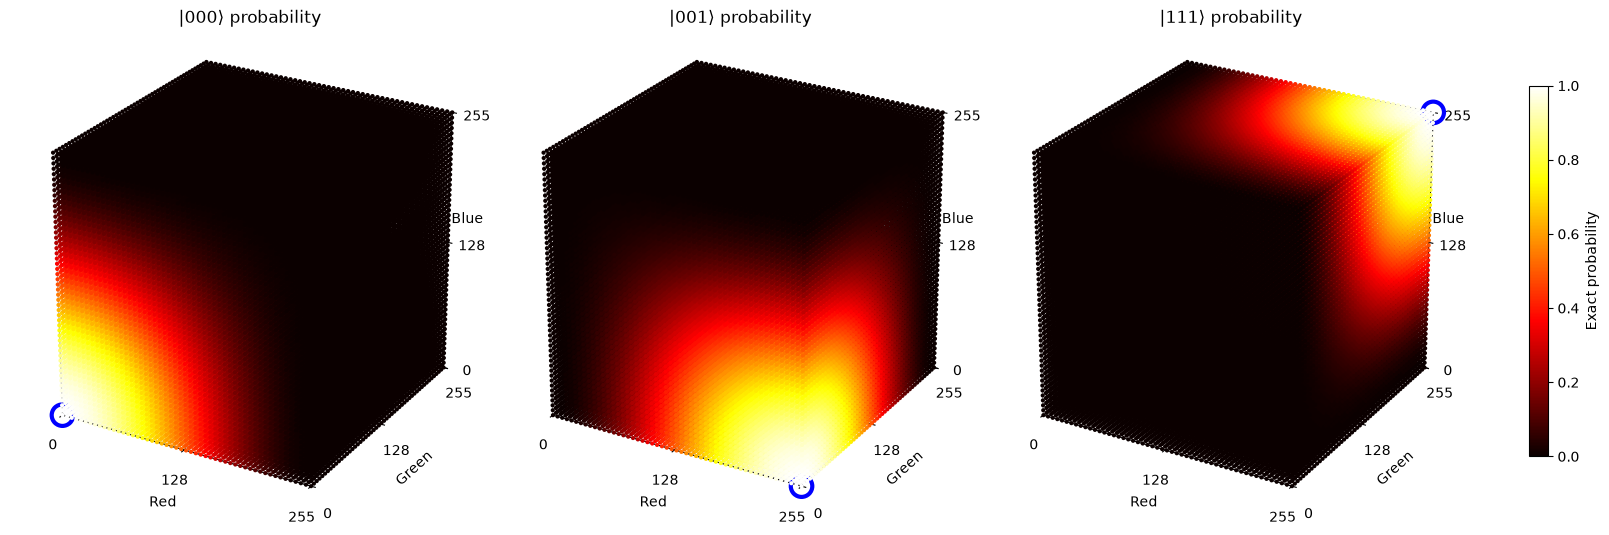
Probability concentrates near black for \(|000\rangle\), red for \(|001\rangle\), and white for \(|111\rangle\). At each marked corner the corresponding outcome is certain. Moving away changes the three channel factors continuously. These are dense point clouds: the visible outer faces occlude interior points. The next plot exposes the entire grid in a different projection.
The probability clouds against distance from black
We now collapse the input coordinates to \(d=\|\mathrm{RGB}-(0,0,0)\|_2\), from 0 to \(255\sqrt{3}\approx441.7\). For each input, we retain four probabilities: all three zeros, exactly two zeros, exactly one zero, and no zeros. A group’s probability is the sum of its member-state probabilities, not their average:
rgb_distances = np.linalg.norm(rgb_grid, axis=1)
zero_counts = np.asarray([state.count("0") for state in state_labels])
probabilities_by_zeros = {
    count: rgb_probabilities[:, zero_counts == count].sum(axis=1) for count in range(4)
}
np.testing.assert_allclose(sum(probabilities_by_zeros.values()), 1, atol=1e-14)
plot_rgb_distance_clouds(rgb_distances, probabilities_by_zeros)
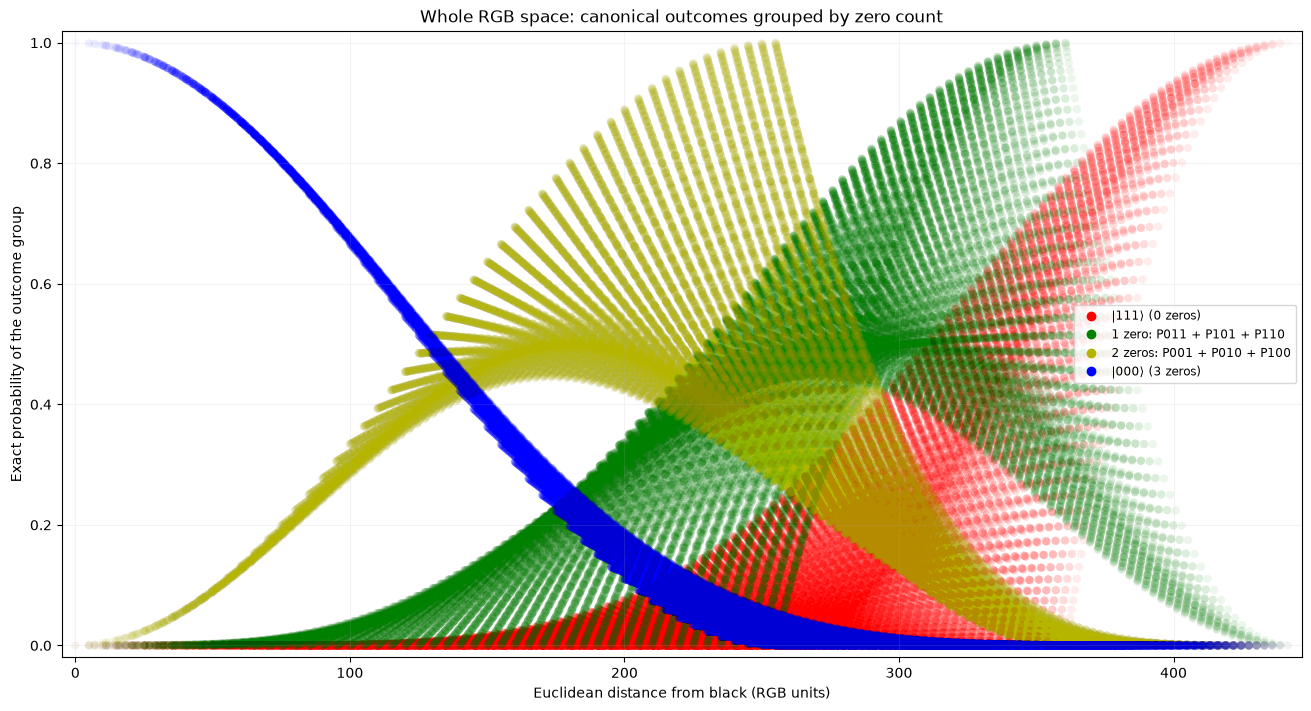
The overlapping fans are the result of projecting a three-dimensional grid onto one distance axis. Every input contributes one point to each group; no curve fitting, averaging, or distance binning is applied. Their fine bands come from the regular RGB sampling, and opacity makes overlapping points appear darker.
Distance alone does not determine the probabilities. For example, normalized inputs \((1,0,0)\) and \((1/\sqrt{3},1/\sqrt{3},1/\sqrt{3})\) are both 255 RGB units from black. The first has \(P_{000}=0\), while the second has \(P_{000}=\cos^6(\pi/(2\sqrt{3}))\approx0.055\). The model responds to the individual channel differences, not just their Euclidean norm. This explains why these are clouds rather than single-valued confidence curves.
Black produces three zeros with certainty; a primary-color corner produces
two, a secondary-color corner one, and white none. Intermediate inputs spread
probability across groups. Later, ZeroBurst assigns these groups intensities
\(1\), \(2/3\), \(1/3\), and \(0\), respectively. First, we need to move the reference
from black to an arbitrary query color.
Querying for similarity to a color
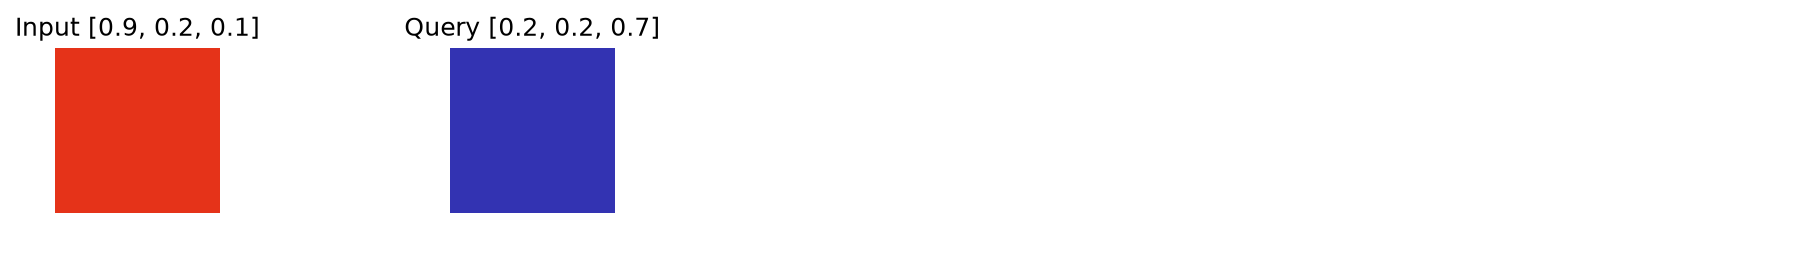
The whole-cube plots used the canonical zero state (black) as the reference. To compare against another color, keep a warm-red input fixed and use a blue query:
fixed_input = [0.9, 0.2, 0.1]
fixed_query = [0.2, 0.2, 0.7]
plot_fixed_input_and_query(fixed_input, fixed_query)
A query changes the basis in which the encoded input is measured. Given a normalized target color \(\bar{\mathbf{x}}\), it applies an inverse rotation to every qubit:
This maps an input equal to the query onto \(|000\rangle\). After this basis
change, the state vectors can no longer be mapped to an RGB color. For each channel,
alignment makes the 0 outcome more probable and mismatch makes the 1 outcome more
probable. After measuring a state, ZeroBurst converts its zero-bit fraction
into a match intensity: how closely the sampled outcome matches the query.
OneBurst provides the complementary mismatch intensity: the sampled outcome’s
fraction of bits that differ from the query-mapped zero state.
The next cell encodes a fixed input, applies the query transformation, and samples the queried model:
queried_model = AngularModel(n=3, tau=1)
for dim, value in enumerate(fixed_input):
    queried_model.encode(value, dim)
queried_model.query(fixed_query)

query_shots = 100_000
queried_counts = queried_model.measure(query_shots)
plot_queried_measurements(fixed_query, queried_counts, query_shots)
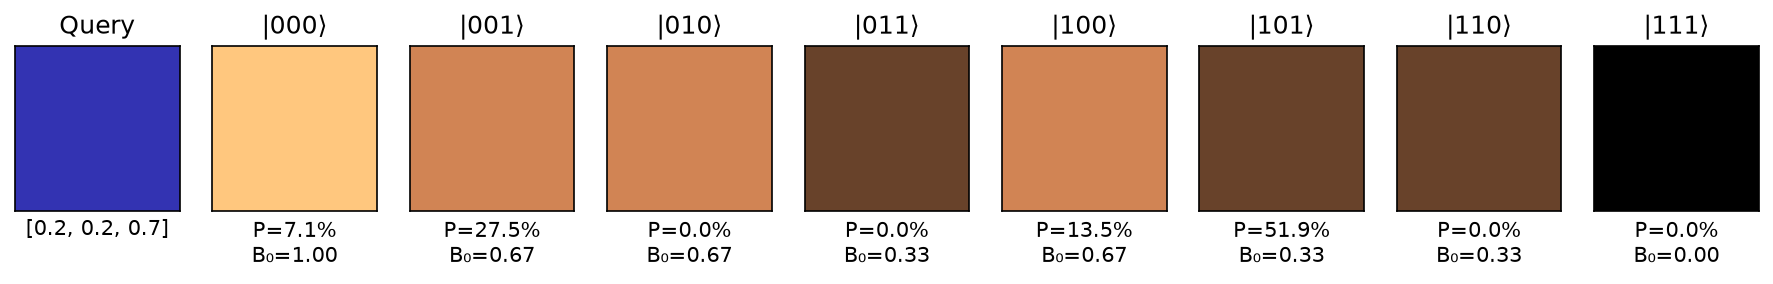
The tile color now represents “how much the input is similar to my query”
(that is, the ZeroBurst value). With the color code we used here, darker
copper means fewer matching channels, and lighter copper means
more. The probability \(P\) answers “how likely is this pattern?”,
while \(B_0\) answers “what match intensity is emitted if this pattern is
sampled?”
Measurement changes w.r.t. varying query (with fixed input)
We can now hold the same input constant while moving the query through RGB space. First, recall the fixed warm-red input:
plot_varying_query_input(fixed_input)
The query follows a piecewise RGB path from blue to red and then from red to green. Pure red, at the middle of the axis, is the closest point on this path to the warm-red input. The blue and green endpoints each disagree with it strongly in two channels.
query_positions = np.linspace(0, 1, 101)

query_colors = []
for position in query_positions:
    if position <= 0.5:
        blend = 2 * position
        query_colors.append([blend, 0.0, 1.0 - blend])  # blue -> red
    else:
        blend = 2 * (position - 0.5)
        query_colors.append([1.0 - blend, blend, 0.0])  # red -> green

queried_probabilities = {state: [] for state in state_labels}
zero_burst_scores = {state: ZeroBurst()(state) for state in state_labels}
plot_query_color_path(query_colors)
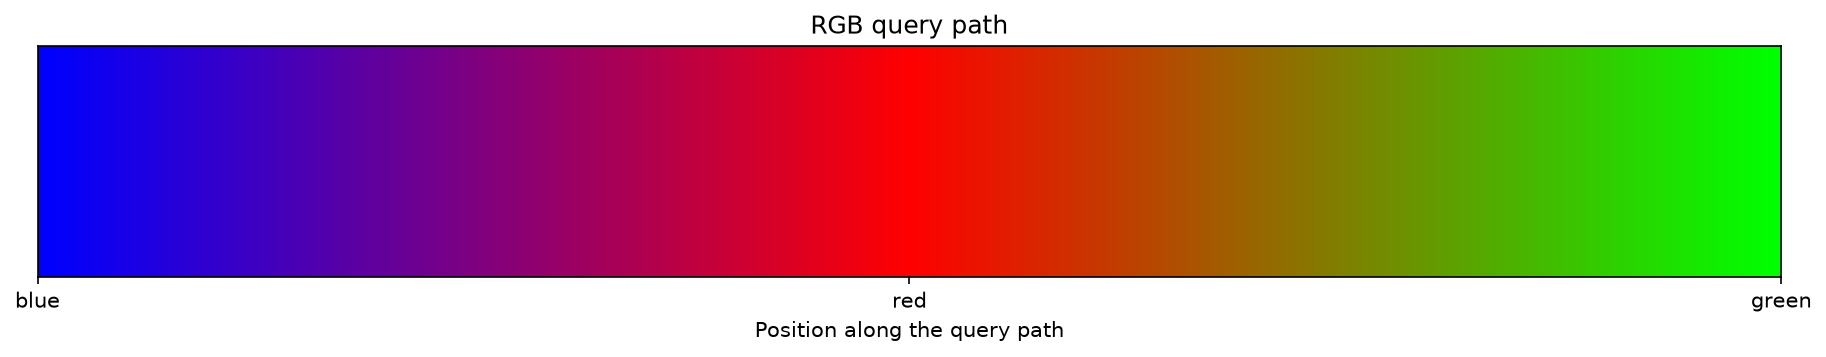
At every position we re-encode the unchanged input in a fresh model, apply the current query color, and record the exact statevector probabilities after the basis change:
for query_color in query_colors:
    queried_model = AngularModel(n=3, tau=1)
    for dim, value in enumerate(fixed_input):
        queried_model.encode(value, dim)
    queried_model.query(query_color)
    probabilities = np.abs(queried_model.get_statevector()) ** 2
    for index, state in enumerate(state_labels):
        queried_probabilities[state].append(probabilities[index])
plot_color_query_sweep(
    query_positions,
    query_colors,
    fixed_input,
    queried_probabilities,
    zero_burst_scores,
)
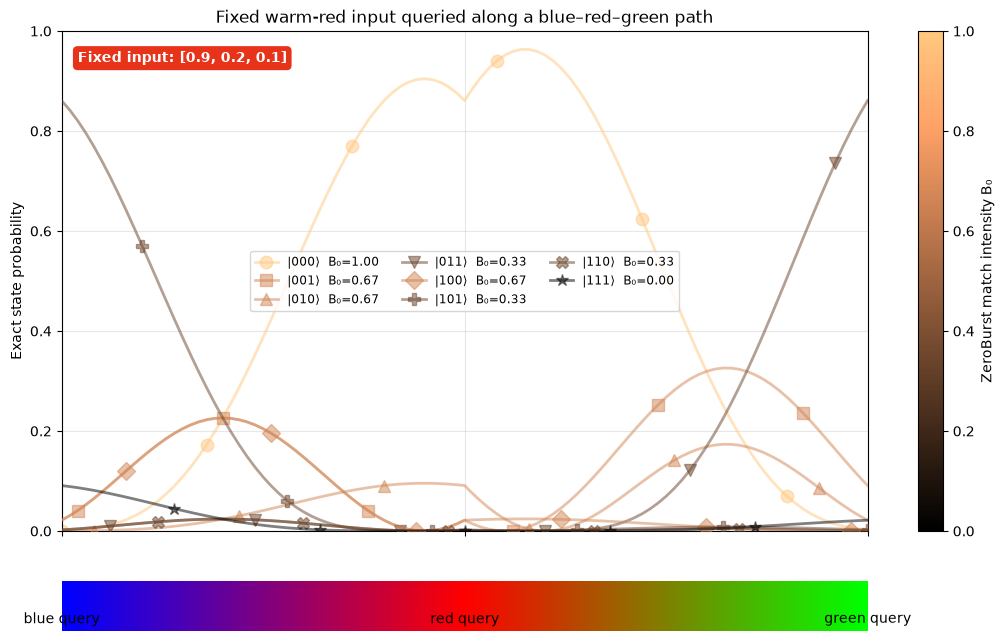
The height of a state curve gives the probability of measuring that state. Its
copper heat color gives the ZeroBurst value emitted if that state is sampled.
The color therefore describes how strongly that particular outcome matches
the query.
Around the red query, states with higher match intensities become more probable. Farther from red, lower-match outcomes become more likely.
We can summarize the complete measurement distribution at every query by
treating each possible ZeroBurst value as a random outcome. The mean is the
average match intensity expected over repeated measurements, while the
standard deviation describes how much individual sampled bursts vary around
that mean:
burst_means = []
burst_standard_deviations = []

for position_index in range(len(query_positions)):
    probabilities = np.asarray(
        [queried_probabilities[state][position_index] for state in state_labels]
    )
    burst_values = np.asarray([zero_burst_scores[state] for state in state_labels])
    mean = np.sum(probabilities * burst_values)
    variance = np.sum(probabilities * (burst_values - mean) ** 2)
    burst_means.append(mean)
    burst_standard_deviations.append(np.sqrt(variance))
plot_burst_summary(
    query_positions,
    query_colors,
    burst_means,
    burst_standard_deviations,
)
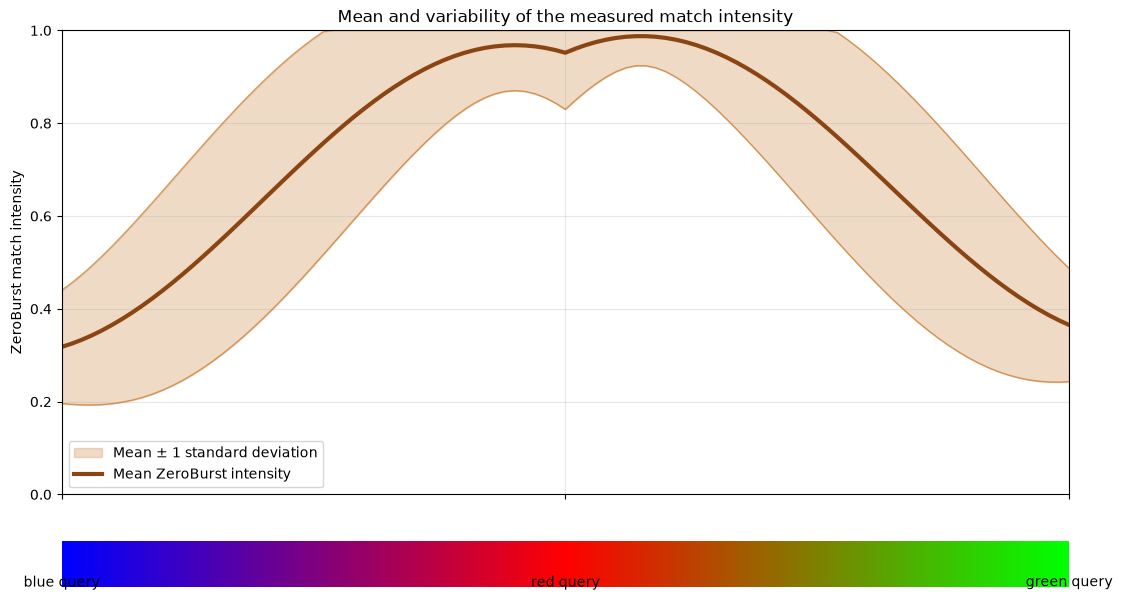
In the plot above, the central line shows the overall output, and the shaded band shows one standard deviation on either side. The values are computed from exact state probabilities, so the band represents intrinsic measurement variability rather than finite-shot sampling noise.
References
D. Lanza, P. Solinas, and F. Mastrogiovanni, Multi-sensory Integration in a Quantum-Like Robot Perception Model, Experimental Robotics, 2021; arXiv:2006.16404.
D. Lanza, Quantum-like Modeling of Cognitive Architectures for Robotics, Zenodo, 2020.